
Projects
A selection of the systems, methods and collaborations we are working on.
SOFAIR
We are developing systems and algorithms to train frontier AI models across wide-area networks of heterogeneous compute. Our contribution to SOFAIR explores how shared GPU infrastructure can pool resources across institutions and better manage demand on the power grid.
The Red Queen Gödel Machine
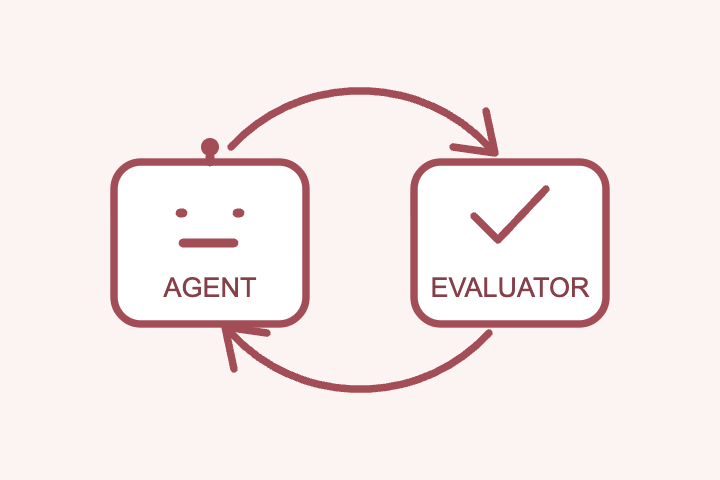
Can AI systems keep improving when the tests used to evaluate them become a bottleneck? We develop agents whose evaluators evolve alongside them, allowing both to improve beyond the limits of a fixed test.
SPRIND
Through CambridgeFlower, we are extending Flower to train AI models across decentralised, heterogeneous hardware. In SPRIND’s Composite Learning Challenge, we develop scalable training systems that let organisations combine their compute while keeping data local.
Wide-area distributed training
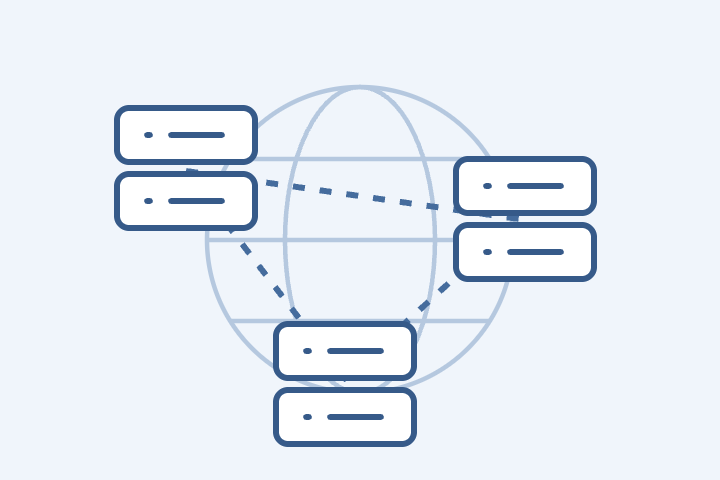
We develop systems and optimisation methods for training large models across geographically distributed GPUs. Our work reduces communication and memory requirements and enables collaborative training across diverse hardware and data sources.
DANTE
We develop and open-source scalable decentralised machine learning methods that let organisations learn from distributed data while protecting privacy and share compute efficiently and securely. DANTE aims to widen participation in advanced AI, support collaboration in sensitive domains such as healthcare, and keep the technology accessible to public services and infrastructure.